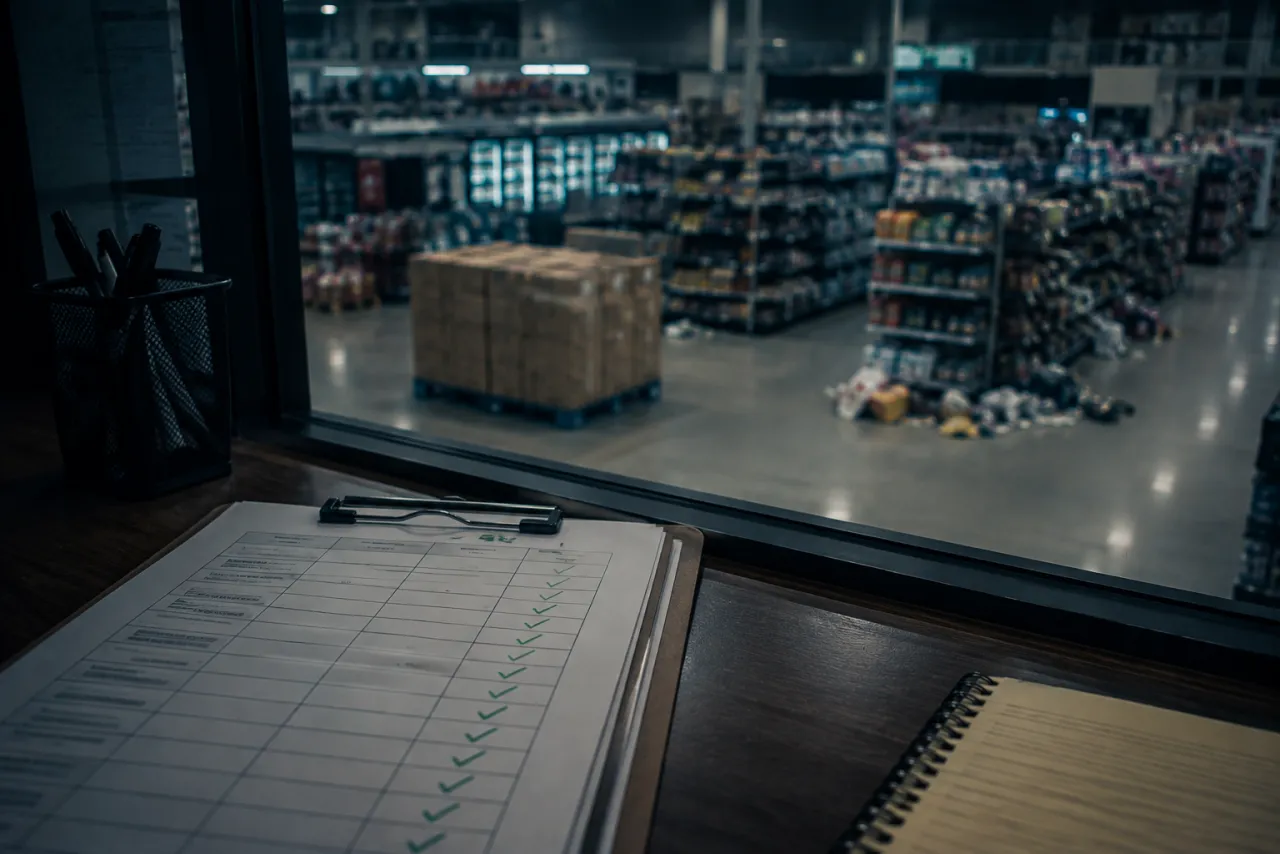
The regional manager’s visit went beautifully. The floor was faced, the restrooms were spotless, both greeters stood in position, and the compliance binder sat open on the office desk. Everyone had known he was coming Tuesday at ten. The store he inspected was real for exactly one morning.
This is the puzzle of store reporting accuracy. Your reports say green. Your customers, your reviews, and eventually your comp sales say something else. The tempting explanation is that somebody is lying to you. Almost always, nobody is.
Reports drift from reality the way light bends through water: not because the water is dishonest, but because bending is what the medium does. Three structural filters sit between the sales floor and your inbox. Name them and you can correct for them. Blame them on character and you will fire good people and change nothing.
Store Reporting Accuracy Is a Systems Problem
Here is the test. If you replaced every store manager in your chain tomorrow, would the reports get more accurate? For a month, maybe. Then the same incentives, the same announced visits, and the same summarizing layers would bend the new people’s reports exactly the way they bent the old ones. When an outcome survives a full change of personnel, the cause is the system, not the people standing in it.
Filter One: Incentives Shape the Pen
When the person filling out the checklist is the same person graded on its result, the checklist becomes homework graded by the student. That does not produce lies. It produces generosity. Every ambiguous item quietly resolves toward yes: the backroom is “organized,” the planogram is “substantially set,” the training is “complete” because the video played in the breakroom while people worked.
Run a hypothetical. Suppose a 40-item self-audit contains six judgment calls, and a manager under a compliance bonus resolves each doubtful call in the store’s favor. A store that an outside observer would score in the mid-80s reports a 97, and not one answer on the form is a false statement. Multiply that small kindness across every store, every week, and your dashboard inherits a permanent optimistic tilt.
Filter Two: The Announced Visit Measures the Announcement
District visits get scheduled. Schedules leak, or are simply shared. So the store gets two weeks of runway: extra payroll shifted to visit day, a deep clean the night before, the promo display finally built. The visit goes fine, the notes go up the chain, and everyone believes them, because everything in them was true.
But you did not measure the store. You measured the store’s ability to prepare for a measurement. Your customers never shop the prepared version. They shop the Tuesday-at-six version, the short-staffed Saturday version, the version nobody photographed. The gap between those two stores is precisely the part of your operation that no announced process can ever see.
Filter Three: Good News Travels, Caveats Die
The third filter is compression. A store note becomes a district summary, becomes a regional rollup, becomes one cell on an executive dashboard. Each layer is written by someone whose own performance the summary describes, and each layer strips a little texture.
- Hedges disappear. “Mostly complete, two gaps remain” becomes “complete.”
- Evidence detaches. The photo stays in a phone; the adjective travels up instead.
- Chronic issues normalize. The cooler that has been down for a month stops appearing in reports at all, because it is no longer news.
- Bad news waits for its fix. Problems get held until they can be reported in the past tense.
None of these steps is a lie. Each is a reasonable editorial choice. Stack three of them and an honest field note arrives at headquarters as a green cell.
The Fix Is Independent Sampling, Not Blame
You cannot exhort your way out of a structural filter, and you should not interrogate your way out either. The fix is a second data stream that none of the three filters can touch: unannounced, anonymous visits on ordinary days, documented by someone with no stake in the score. In our work every finding must be backed by a photo, a timestamped note, or a receipt, and every report passes internal QA before you see it; the full chain is described in how reporting works. This is observation, not investigation. Nobody is being caught. Reality is being sampled.
The comparison is the payoff. Where the self-report and the independent sample agree, trust your reporting and stop double-checking it. Where they diverge repeatedly, you have found a filter, and often something deeper: a store where practice has quietly drifted away from policy because a metric made the drift rational. That specific pattern is what our Policy Drift and Metric Pressure Audit is designed to surface. And if this sounds like mystery shopping, it is a different discipline with different evidence standards; we drew the line in mystery shopping vs. field intelligence.
Calibrate the Instrument Before You Blame the Reading
Your reporting system is an instrument, and every instrument needs calibration against an outside reference. A modest independent sample tells you how far your reports sit from reality, in which direction, and in which stores, without a single accusation being made.
The simplest calibration we offer is the 10-store pilot: $7,500 all-in for ten unannounced anonymous visits, photo-backed severity-scored reports, an aggregated findings summary, and a one-hour executive debrief, completed in three to five weeks with no long-term commitment. Pull the self-reports those same ten stores filed this month, set the two stacks side by side, and talk to us about what the distance between them means.